Features Pipeline Architecture Stack
OmniSuite

OmniSuite

A full desktop platform for AI-assisted music production. Song generation, audio analysis, mixing, mastering, vocal production, image gen, video creation — all in one interface, all running locally.

Python / FastAPI pywebview Desktop RTX 5070 Ti Local-First
Screenshots

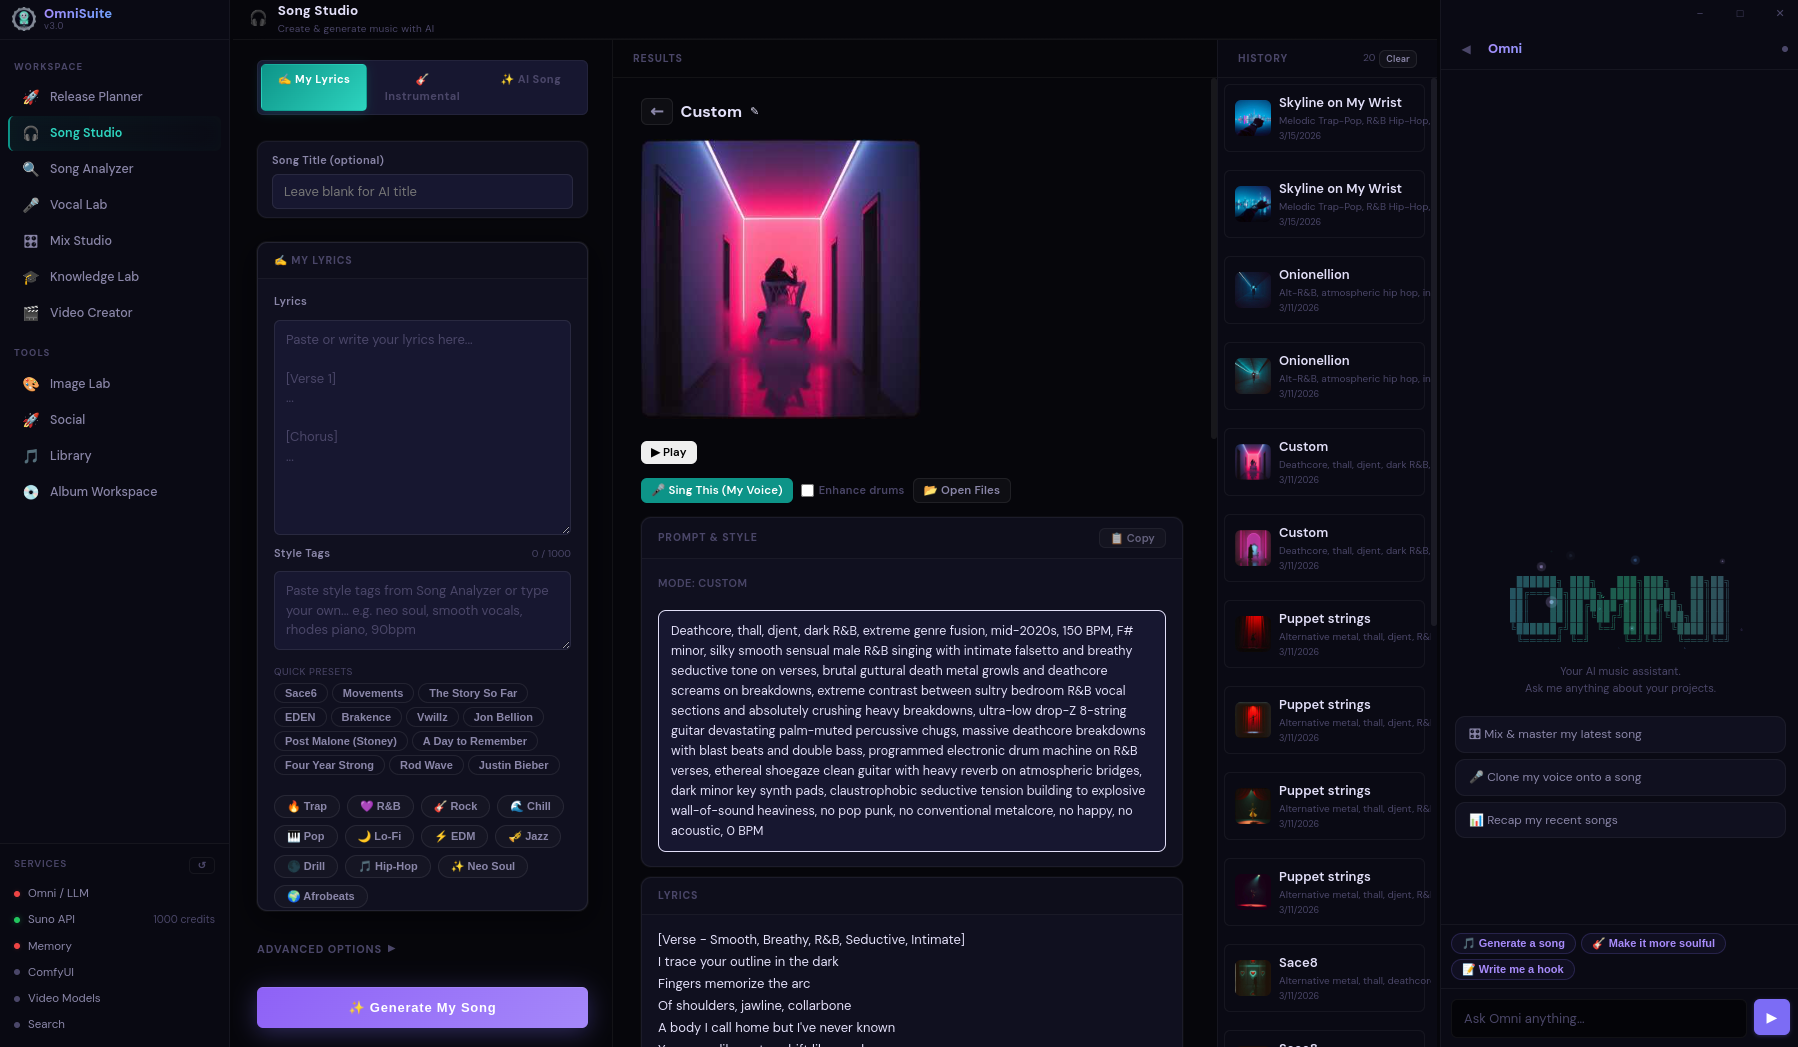
OmniSuite Song Studio

Song Studio — Generation, Lyrics, Cover Art, Prompt Engineering

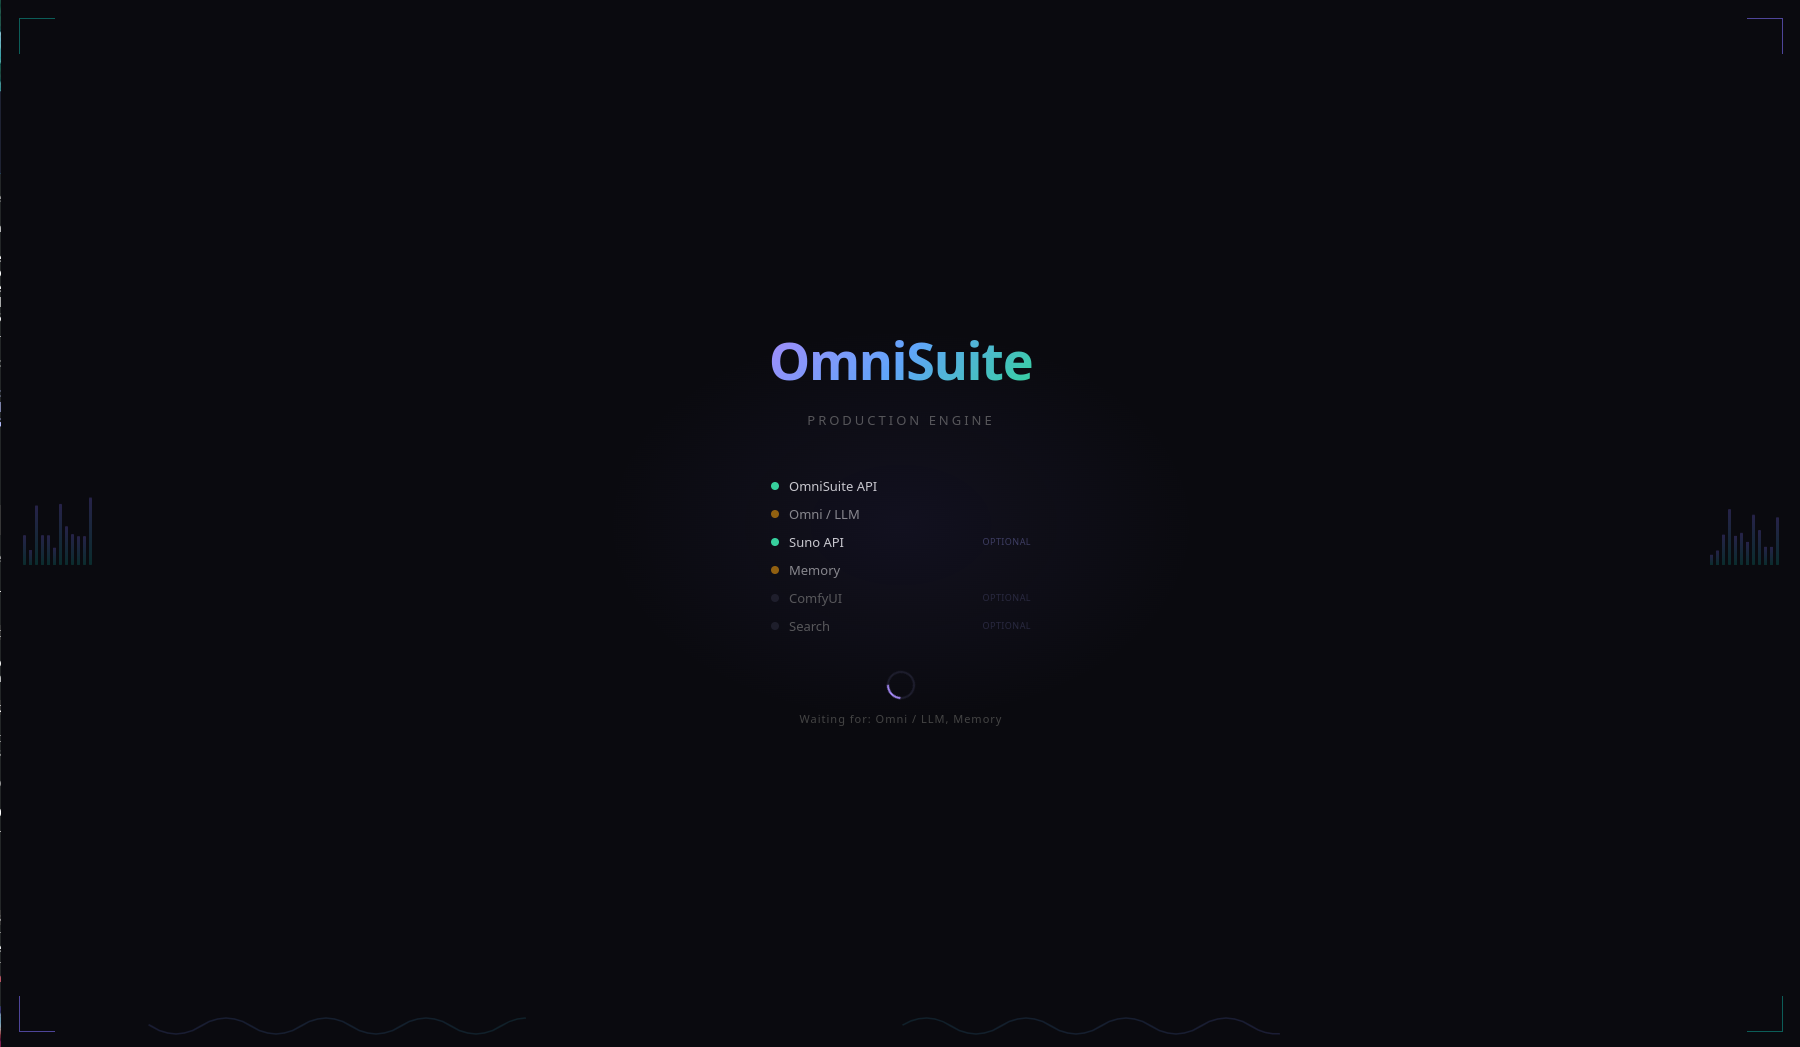
OmniSuite Launch Screen

Launch — Service Health Check

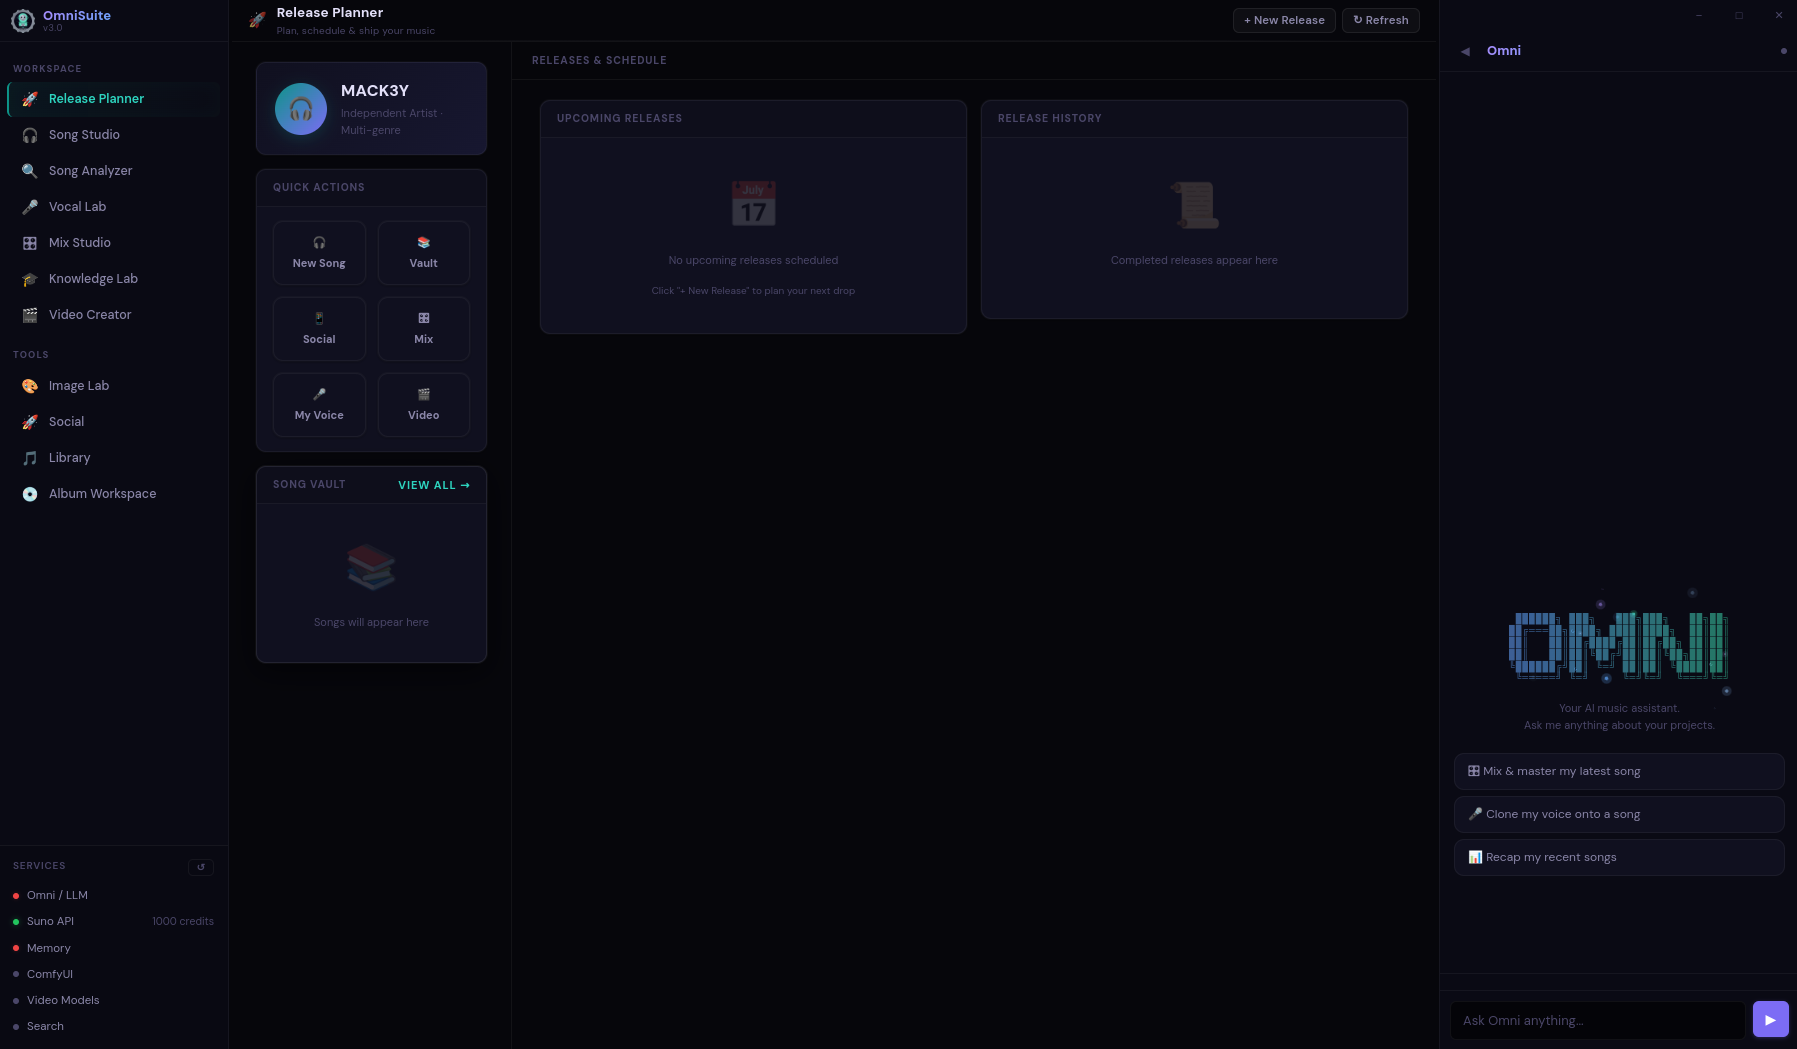
OmniSuite Release Planner

Release Planner — Dashboard

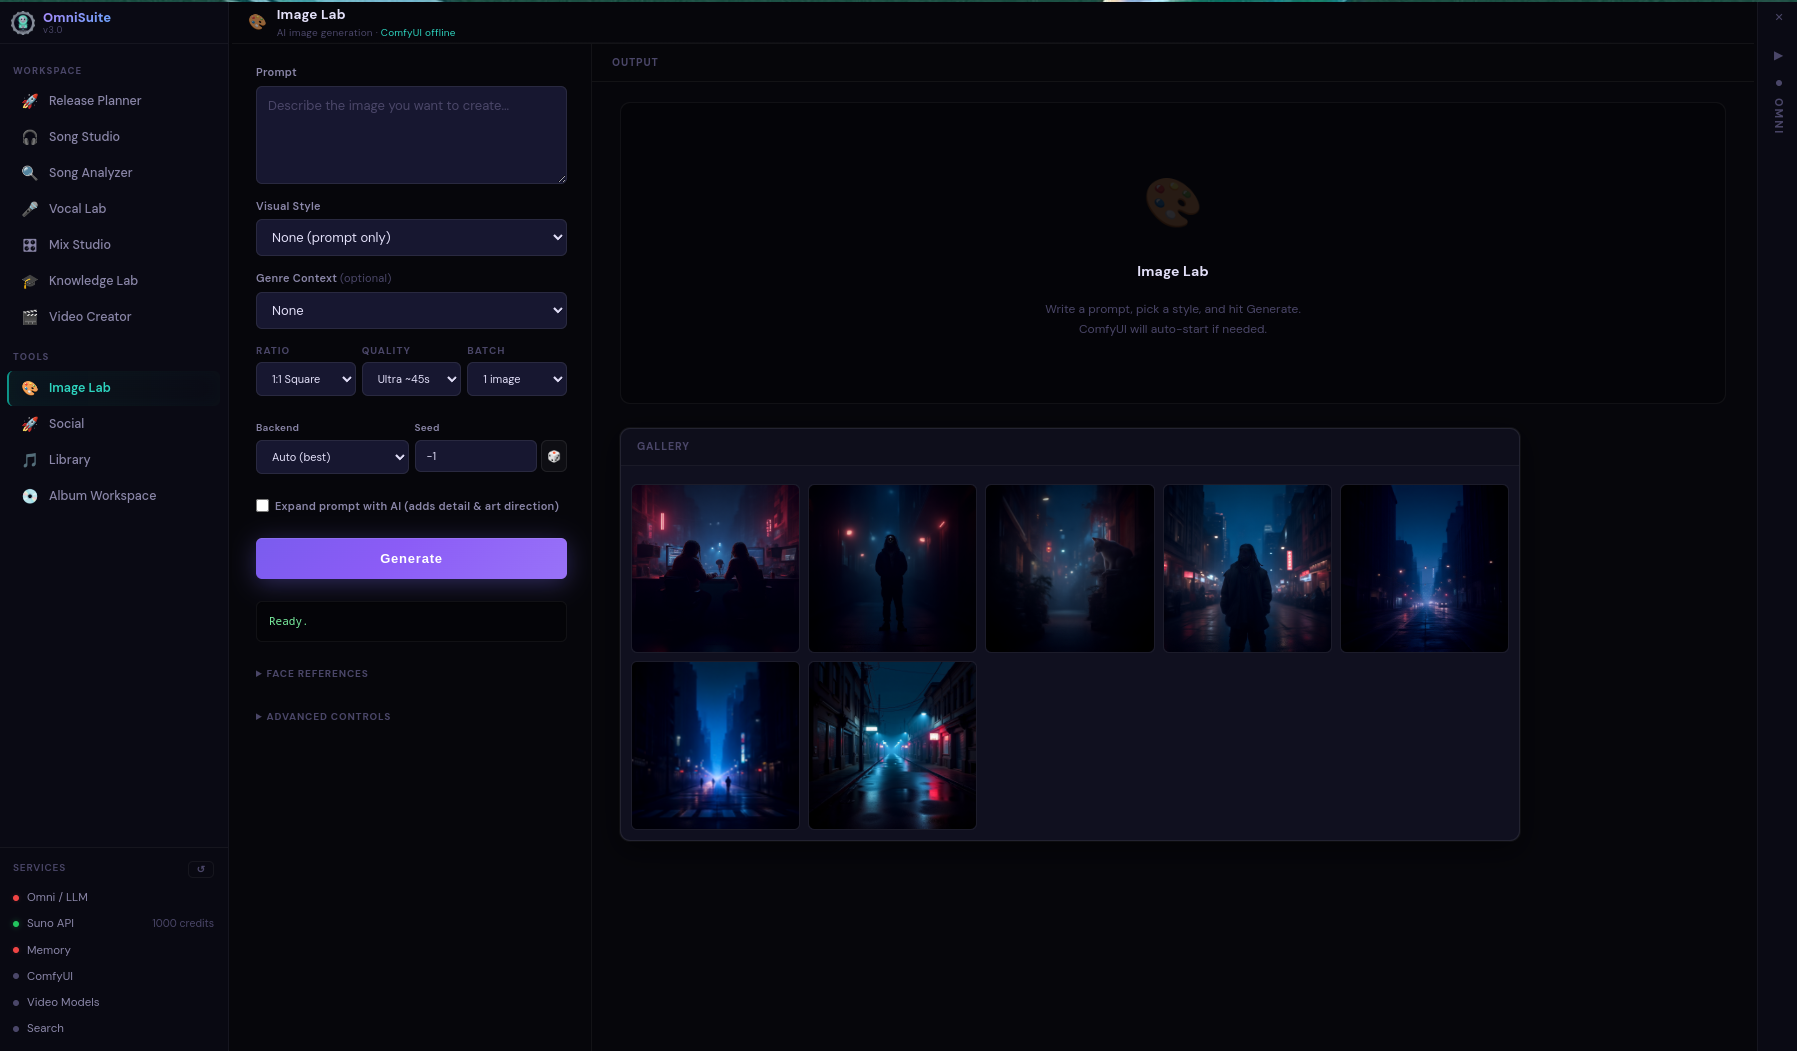
OmniSuite Image Lab

Image Lab — Local Generation

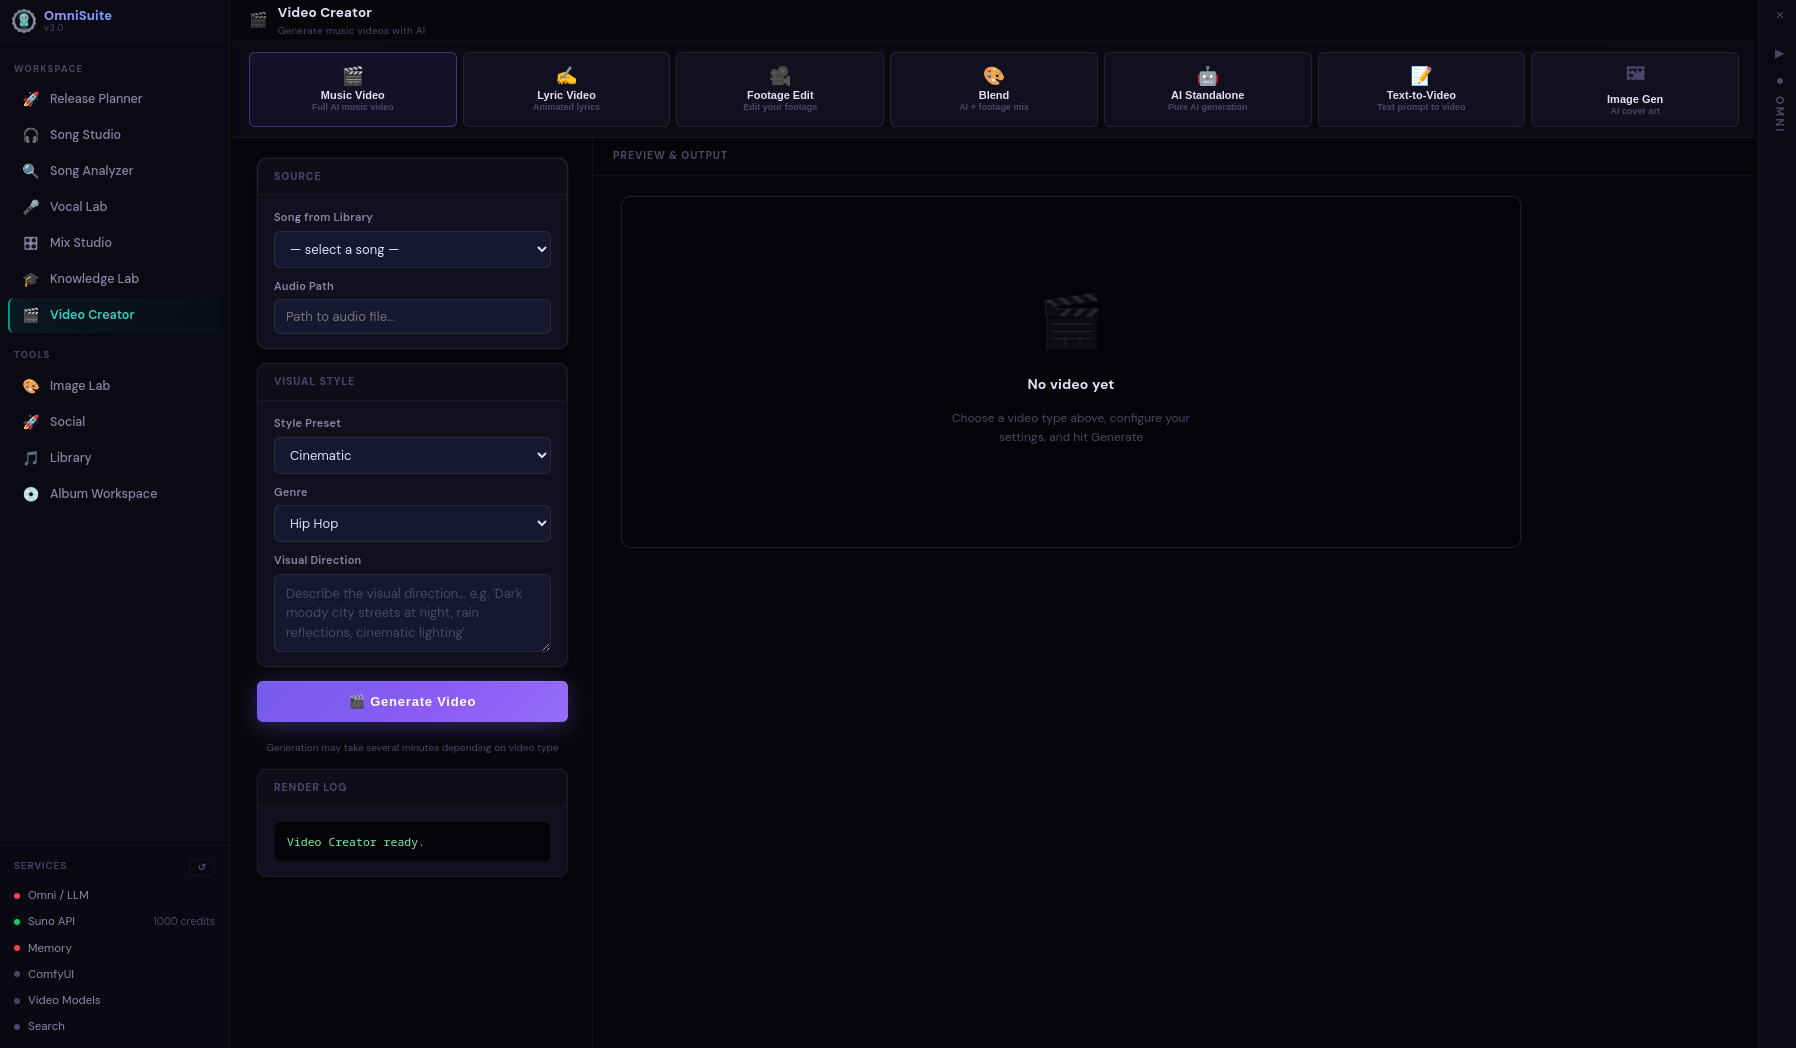
OmniSuite Video Creator

Video Creator — Music Video Pipeline

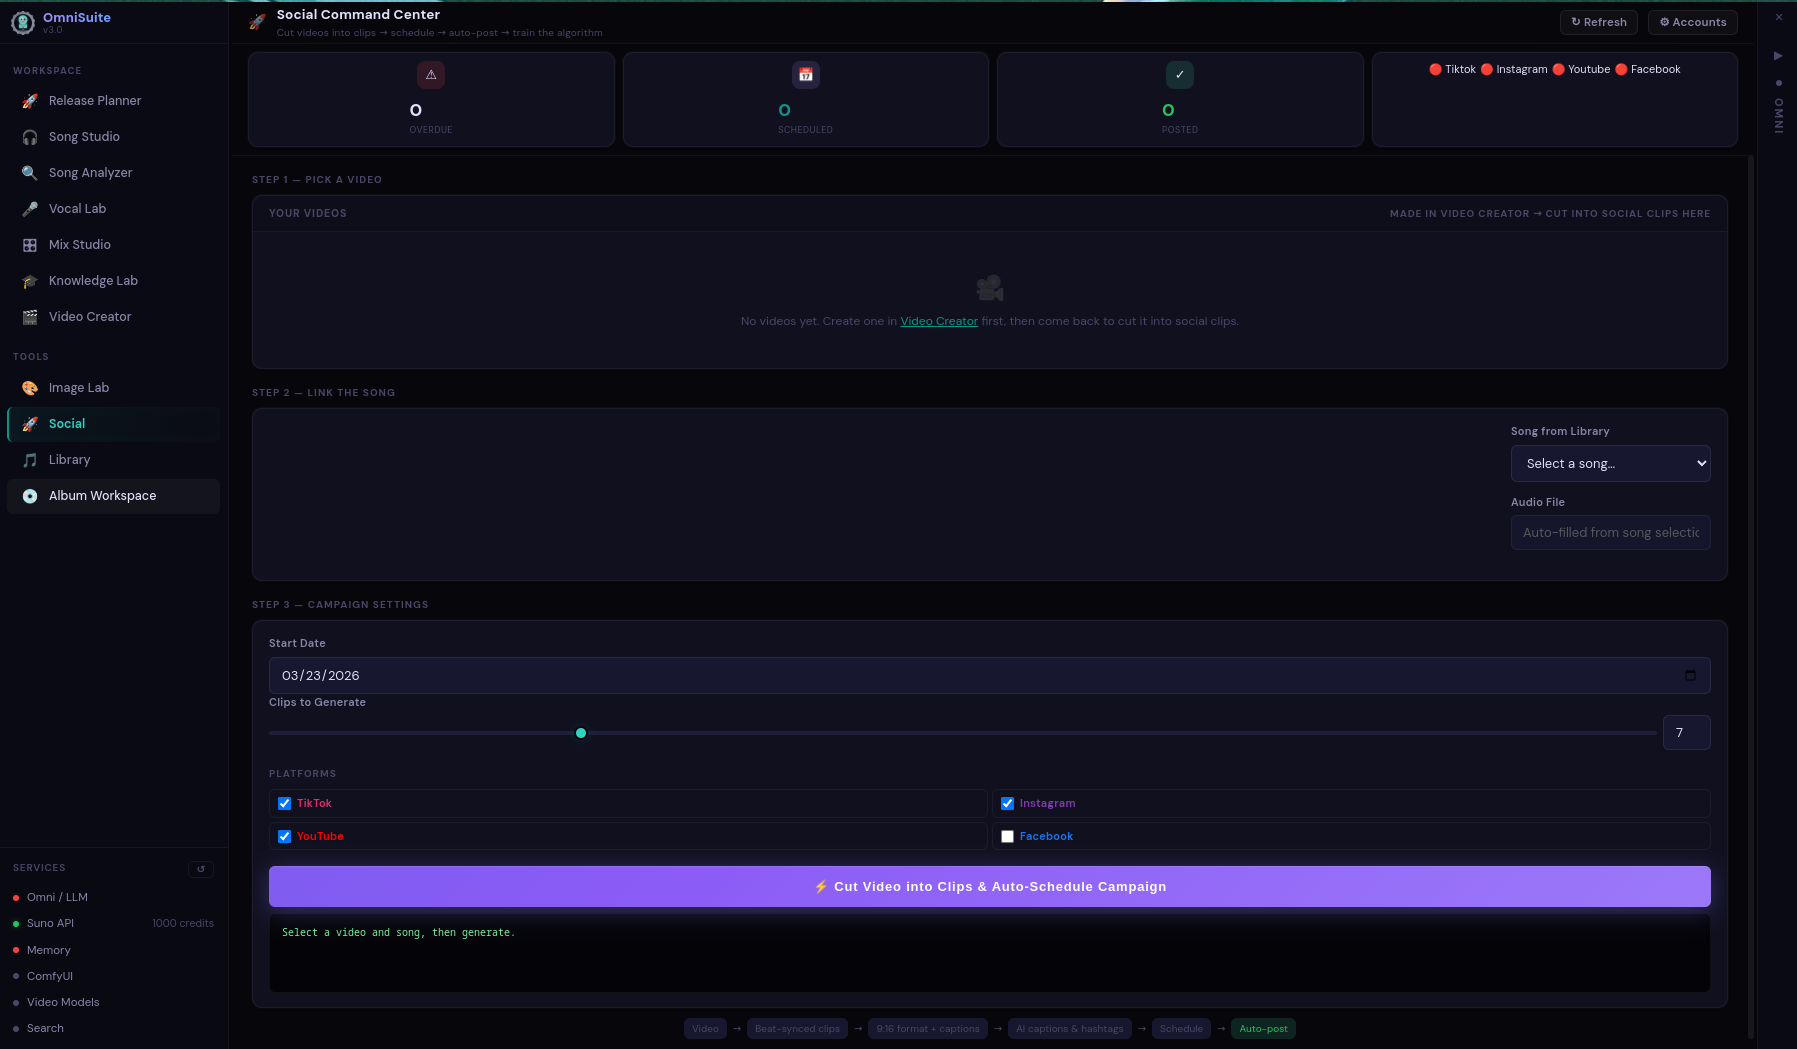
OmniSuite Social Command Center

Social Command Center

Features

Built because the tools I wanted didn't exist. Every module runs locally on my own hardware — no cloud dependencies for core functionality.

🎵

Song Generation

SSE-streamed generation with real-time progress, automatic captcha solving, and 73 few-shot genre examples that teach the model what good prompts look like. Full vocal chain enforcement in every prompt.

📊

3-Tier Audio Analysis

Gemini for fast analysis, librosa + LLM for deep BPM voting and Krumhansl-Schmuckler key detection, offline fallback when nothing's available. 16-profile genre fingerprinting.

🎛

Mix & Master Engine

14 genre presets with per-stem frequency pockets. Resolves Suno WAV stems, falls back to Demucs separation. LUFS-targeted mastering chain with genre-aware EQ, compression, and limiting.

🎤

Vocal Production

10-stage LA studio vocal chain. Per-layer pitch detection via pyin — lead, harmonies, and ad-libs all processed independently through the full production pipeline.

🎶

Stem Separation

Demucs + UVR5 pipeline. Kim Vocal 2 for separation, de-reverb and de-echo passes for clean stems. decompose_stem() splits every vocal layer for independent processing.

🎨

Image Generation

Fully local pipeline — nunchaku, FLUX.1-dev, SDXL backends. No cloud fallback. Album art, promotional images, video thumbnails. All generated on-device with the RTX 5070 Ti.

🎬

Video Pipeline

5-tier music analysis feeds an LLM director that generates shot lists and treatments. 54 genre-specific color grades via FFmpeg. Beat-synced editing with parallax Ken Burns fallback.

✍

Lyrical AI

ChromaDB knowledge base with 452 documents and 294 artist profiles across 13 genre groups. Universal craft principles injected on every generation. Context-aware retrieval from session history.

🎸

Instrument Lab

Full 10-stage instrument replacement pipeline. MusicGen and Stable Audio stem generation, audio super-resolution, seamless mixing back into the original track.

The Pipeline

From idea to finished, mastered track with your own voice — this is what a full run looks like.

01

Prompt Engineering

Genre-first prompt with BPM number, full 5-element vocal chain, mood tags. 73 few-shot examples + knowledge base guide the generation. 440-490 characters enforced.

02

Song Generation

SSE-streamed via Suno with automatic captcha solving (Playwright + 2captcha). Real-time progress in the UI. Per-clip fallback for failed fetches.

03

Audio Analysis

3-tier analysis extracts BPM (multi-method voting), key (Krumhansl-Schmuckler), genre fingerprint, energy profile. Feeds downstream mixing and video decisions.

04

Stem Separation

Demucs splits into vocals, drums, bass, other. UVR5 de-reverbs and de-echoes. decompose_stem() further isolates lead, harmonies, ad-libs.

05

Vocal Production

10-stage chain: noise gate, de-ess, compression, EQ, saturation, stereo width, delay, reverb, limiter, final gain staging. All via pedalboard.

06

Mix & Master

Genre preset selects per-stem frequency pockets. Mix bus processing, then master chain targeting genre-specific LUFS. Output: radio-ready WAV.

07

Visual Production

Image gen for artwork, video pipeline for music videos. LLM-directed shot lists, beat-synced cuts, 54 color grades. LTX-Video for I2V animation.

Architecture

Desktop app with a FastAPI backend and pywebview frontend. Docker sidecar for Suno API. Two Python virtual environments — one for the app, one for ML.

Backend

Python/FastAPI on uvicorn (port 8420). SSE endpoints for all long-running operations. Async throughout. ChromaDB for knowledge retrieval and session memory.

Frontend

Single HTML file rendered in pywebview. No framework, no bundler — vanilla JS with a persistent chat overlay and tabbed workspace. Context menus for song operations.

ML Environment

Separate ml-venv (Python 3.12) with PyTorch nightly cu128 for the RTX 5070 Ti. Demucs, MusicGen, Stable Audio, audio-separator all isolated here.

Docker Sidecar

Suno API wrapper runs in a Docker container on port 3040. Playwright-based captcha solving with 2captcha. Clerk auth fallback for direct API access.

Knowledge Layer

Two ChromaDB collections: omni_knowledge (22 structured docs) for system context, lyrics_guides (452 docs, 294 artist profiles) for lyrical generation. Synced via custom script.

Audio Engine

pedalboard for real-time audio processing. librosa for analysis. FFmpeg for format conversion. Everything processed as 44.1kHz WAV internally.

Tech Stack

LanguagePython 3.14 (app) + 3.12 (ML)
BackendFastAPI + uvicorn
Frontendpywebview + vanilla JS
MLPyTorch nightly (CUDA 12.8)
GPURTX 5070 Ti (16GB VRAM)
Audiopedalboard, librosa, Demucs, UVR5
Audio FXpedalboard (10-stage vocal chain)
ImageFLUX.1-dev, SDXL, nunchaku
VideoFFmpeg, LTX-Video, moviepy
KnowledgeChromaDB (474 documents)
ContainerDocker (Suno API sidecar)
PlatformLinux (CachyOS / Arch)
PythonFastAPIpywebview PyTorchCUDA 12.8Docker ChromaDBDemucs FFmpegFLUXSSE pedalboardlibrosaUVR5 MusicGenLTX-VideoPlaywright